Best Free OCR for PDF Files With No Watermark: Six Options Compared
What each free OCR route gives you back, what it can't do, and which one fits your scan.
The best free OCR for PDF depends on what you need back. For a searchable PDF of an English scan, our OCR PDF tool does it online with no account and no watermark; for other languages, Google Docs or the open source Tesseract engine are the stronger free picks.
None of the six options below stamps a logo on your text. They differ in languages, file limits and whether you get a PDF or plain text.
Free OCR Options for PDF at a Glance
| Option | What you get | Languages | Limits worth knowing |
|---|---|---|---|
| OCR PDF on pdf-file.com | Searchable PDF, same look as the scan | English only | 25 MB per file, several files per run |
| Google Drive and Google Docs | Editable Google Doc with the text | Detects the language, from a long list | 2 MB per file, tables and columns not kept |
| Tesseract (with OCRmyPDF for PDFs) | Text or searchable PDF on your computer | 100+ | Command line, you install it |
| Windows 11 Snipping Tool or PowerToys | Copied text from a screen area | PowerToys: the OCR language packs installed | One area at a time |
| Live Text on a Mac | Copied text from an image | Not all languages, per Apple | One image at a time |
| OnlineOCR.net and OCR.space | Text from an uploaded file (OnlineOCR.net also Word or Excel) | OnlineOCR.net 46; OCR.space 33, or over 200 more with its Engine 3 | 15 MB and 5 files an hour; 5 MB per file |
OCR PDF on pdf-file.com: Searchable PDF Online
OCR PDF runs the Tesseract engine on every page and gives you back a PDF that looks exactly like your scan, with the recognized text laid over it as an invisible layer. You can search it, select words and copy them out. It adds no watermark or logo.
- Upload one or more scanned PDFs, each up to 25 MB.
- Click Run OCR.
- Download the PDF, or a ZIP if you added several files.
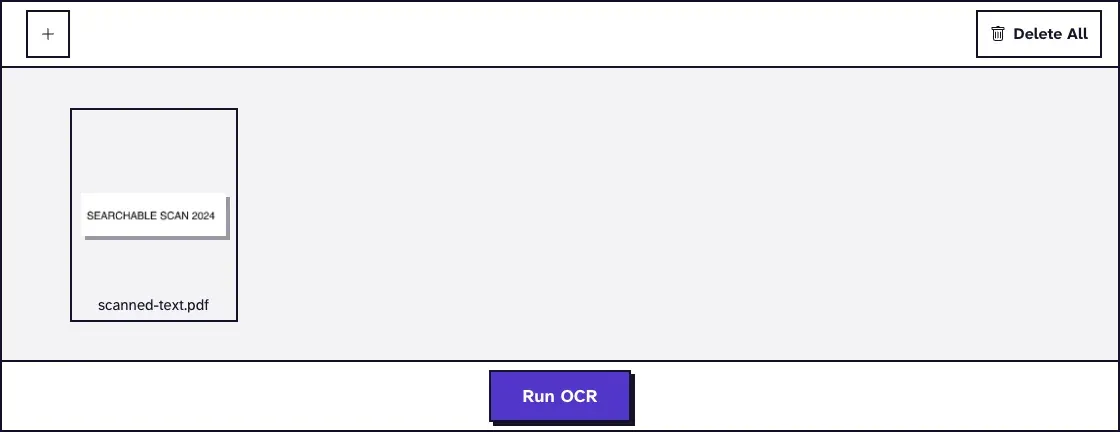
We ran our one-page test scan (16.0 KB) through it in November 2026. The OCR copy came back as an 18.2 KB PDF of the same page size, with the text added.
The limit is language: it reads English only. In our test pages most words with accents came out wrong, 1 of 15 right in Spanish and 0 of 16 in German. Files are deleted automatically within two hours.
How Accurate Free OCR Is on a Real Scan
We ran the same 256-word English page through OCR PDF in November 2026 (Chrome on a Mac) and checked the output word for word. It's one clean page generated by Ghostscript, so treat these as a rough guide.
| Scan | Words read correctly |
|---|---|
| 300 dpi, straight | 256 of 256 |
| 200 dpi, straight | 256 of 256 |
| 150 dpi, straight | 253 of 256 |
| 300 dpi, turned 3 degrees clockwise | 91 of 256 |
| 300 dpi, turned 3 degrees counterclockwise | 202 of 256 |
On this page, tilt mattered far more than resolution. OCR PDF doesn't straighten pages, so if your scan is crooked, deskew it first with a tool that does, such as OCRmyPDF.
Google Docs: Free OCR for Files Up to 2 MB
Google Drive turns a PDF or image into an editable Google Doc. According to Google's help page on converting PDFs to text in November 2026, the file must be 2 MB or smaller, the text at least 10 pixels high and the pages right-side up.
- Upload the PDF to Google Drive.
- Right-click it and choose Open with, then Google Docs.
- Copy the text or download the document in the format you need.
Google says bold, italics and line breaks are likely to be kept, while lists, tables, columns and footnotes are not likely to be detected. You need a Google account, and you get a document, not a searchable PDF.
Tesseract and OCRmyPDF: Free OCR on Your Own Computer
Tesseract is the open source OCR engine behind many tools, ours included, under the Apache 2.0 license. Its trained models cover 100+ languages, and you can load several at once for mixed-language pages.
Tesseract reads images, not PDFs. OCRmyPDF, a free open source wrapper, handles that part and writes a searchable PDF. Our guide to OCR in more than one language shows how to run Tesseract with several languages loaded.
It's the best choice for private documents, since nothing leaves your machine, and for languages our tool can't read.
Built-in OCR on Windows and Mac
On Windows 11, the Snipping Tool's Text actions can pull text from a screenshot, and Microsoft's free PowerToys add a Text Extractor (Win+Shift+T) that copies text from any area of the screen. Open the scan, select the part you need and paste the text.
On a Mac, Live Text lets you copy text from a photo in Preview. Apple says it isn't available in all regions or languages.
Both are quick for a paragraph or a phone number. For a 30-page scan they're tedious, because you work one screen area at a time.
Online OCR Sites: OnlineOCR.net and OCR.space
Free OCR websites return the text of an uploaded file, so there's no watermark to worry about. As we read their pages in November 2026, OnlineOCR.net takes up to 15 MB and 5 files an hour without an account, and OCR.space's free tier takes up to 5 MB per document.
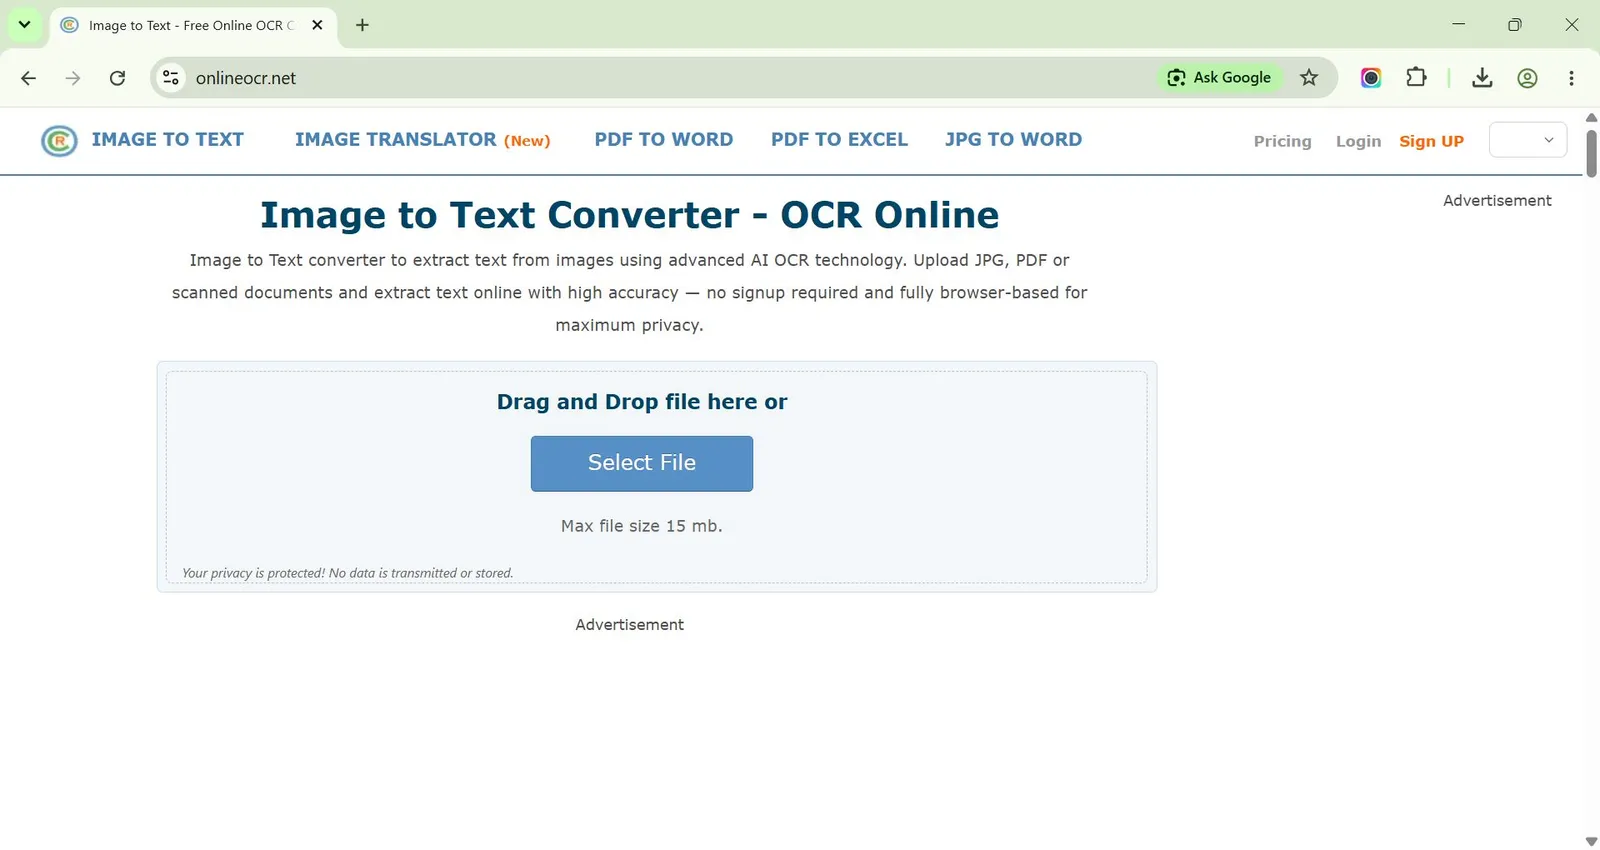
Both say they delete files right after processing, but the file still goes to their server, so read their privacy terms before you upload contracts or IDs.
How Much OCR Adds to a Multi-Page Scan
Our 20-page scan went from 4.86 MB to 4.92 MB through OCR PDF, and Compress PDF can bring it well below where it started. We ran 20 different pages of 200 dpi JPEG scan through both tools on our server on 10 November 2026, then read the text back to see if it survived.
| Step | File size | Words still in the file |
|---|---|---|
| Original scan | 4.86 MB | None |
| After OCR PDF | 4.92 MB | 5,160 |
| Then Compress PDF, Light | 4.92 MB, handed back unchanged | 5,160 |
| Then Compress PDF, Recommended | 2.1 MB | 5,160 |
| Then Compress PDF, Max | 0.77 MB | 5,160 |
The text layer stayed at every level. The pictures didn't stay as sharp: Recommended took them from 200 to 130 dpi and Max to 72 dpi, so check that Max is still readable to you.
Watch the 25 MB limit on longer scans. Each page here came out at about 440 KB, and a 100-page test came out at 43.7 MB, which is too big to upload to Compress PDF. Split a long scan into parts before OCR if you'll want to compress the results.
Which Free OCR to Pick
- English scan, want a searchable PDF: OCR PDF.
- Want the text as a TXT file: run OCR PDF, then convert the copy with PDF to TXT. Our guide to extracting text from a scanned PDF covers it step by step.
- Other languages, small file: Google Docs.
- Other languages, big or private files: Tesseract with OCRmyPDF.
- One line from a scan: the Snipping Tool, PowerToys or Live Text.
- Handwriting: expect mistakes from every free tool. Our guide to OCR for handwritten notes explains what works.
Frequently Asked Questions about the Best Free OCR for PDF
Is there free OCR for PDF with no watermark?
Yes. OCR PDF on pdf-file.com, Google Docs, Tesseract and the built-in Windows and Mac tools add no watermark or logo to your text.
Can free OCR read tables?
Partly. The text comes through, but table structure often doesn't. For figures you want in a spreadsheet, run OCR first, then use PDF to Excel and check the cells against the scan.
Why does OCR get some letters wrong?
OCR guesses each character from its shape, so look-alikes such as O and 0 or l and 1 get mixed up, especially on crooked or blurry scans. Check names, numbers and dates by hand.
Does OCR make my PDF bigger?
Only a little, because the page images stay as they were. Our 20-page, 200 dpi scan grew from 4.86 MB to 4.92 MB, and a 16.0 KB one-page scan came back at 18.2 KB. Compress PDF shrinks the result, and the text stays.