
OCR PDF Online: Add Searchable Text to Scanned Pages
OCR PDF reads the text in a scanned PDF and adds it to the file as real text you can search, select and copy. Each page is rendered at 300 dpi and read by the Tesseract OCR engine for English text, then the recognized text goes over the page image as an invisible layer.
// how it works
OCR PDF Online in 4 Easy Steps
- 01Upload your scanned PDF, or drag it here.
- 02Add more scanned PDFs if you need to.
- 03Click 'Run OCR' to pull the text out of your document.
- 04Download your PDF with the recognized text added.
How OCR Turns a Scanned PDF into Text
A scanned PDF is a stack of pictures: you can read it, but you can't search it or copy a sentence out of it. OCR (optical character recognition) finds the letters in those pictures and turns them into real text.
Our OCR PDF tool runs the open source Tesseract engine on every page of your scan and gives you back a PDF with the recognized text in it. You can then search it, select it and paste it somewhere else. Nothing to install, no account.
Run OCR on Your PDF for FreeHow to OCR a PDF online
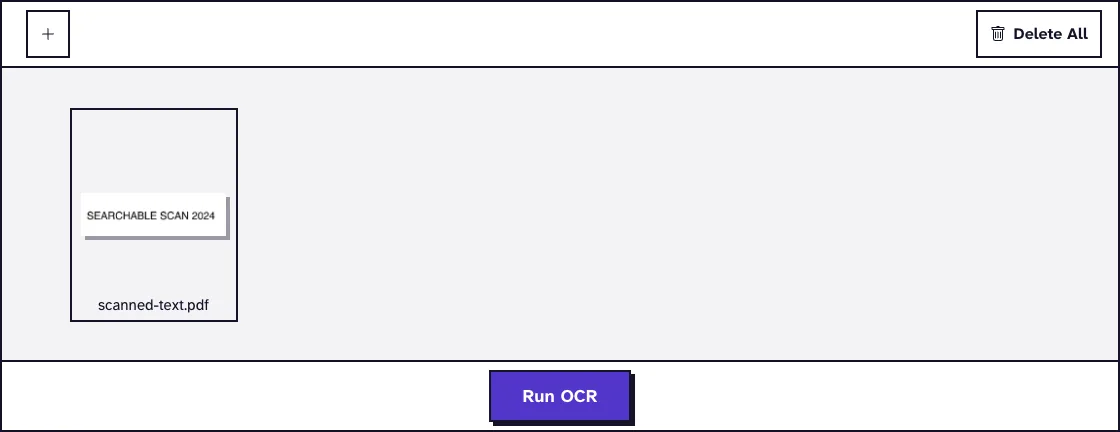
- Click Choose Files or drag your scanned PDF onto the page. Each file can be up to 25 MB.
- Add more scanned PDFs if you've got them. Each one gets its own OCR copy.
- Click Run OCR and wait while every page is read.
- Download your PDF, or a ZIP if you processed several files.
What our OCR tool does to your PDF
First, the tool checks each page for text. A page with 50 or more characters of readable text is left as it is, and so is a shorter one with no picture on it. Ghostscript renders every other page as an image at 300 dpi, and Tesseract reads that image with its English language model.
The recognized text is then laid over the original page as an invisible layer. The page keeps its images, links, size and look, and the file keeps its title and other properties.
A page whose font has no map to letters, so its text copies as symbols, is the exception. That page alone is rebuilt from the 300 dpi picture with Tesseract's text, so the garbled text is gone and the new text copies correctly. On a generated one-page test file like that, on 10 November 2026, the copy grew from 13.7 KB to 53.4 KB and all 45 words came back.
Tesseract puts each word over the spot on the scan where it read it. On a scanned letter we tested in October 2026, all 47 recognized words sat on their printed words, at most 4.8 points off at the edges. So when you search in your reader, it highlights the word on the picture itself.
What happened when we tested OCR PDF
We used scanned-text.pdf, a small test file of 16.0 KB: one page holding a scanned line of text. The tool returned scanned-text_OCR.pdf, 18.2 KB, still 1 page of the same size with the same 144 dpi image, and the recognized text added.
OCR PDF has no options, so the file was processed as uploaded. Tested again on 10 November 2026.
How accurate the OCR was at each scan resolution
To put a number on it, we scanned the same 256-word page at three resolutions and once slightly crooked, then matched the OCR output word for word against the source on 22 October 2026.
| Scan | Words read correctly |
|---|---|
| 300 dpi, straight | 256 of 256 |
| 200 dpi, straight | 256 of 256 |
| 150 dpi, straight | 253 of 256 |
| 300 dpi, turned 3 degrees | 97 of 256 |
A clean 200 to 300 dpi scan read every word, and 150 dpi missed just three. A tilt of only 3 degrees dropped it to 97 of 256, which surprised us. Straightening the page does far more than a higher resolution.
How to get better OCR results
Tesseract's own guide to improving the quality of the output says it works best on images of at least 300 dpi, and that text lines tilted on the page make recognition much worse. Our tool already renders at 300 dpi, so the scan itself is the part you can improve.
Scan straight, in good light, with dark text on a light background. Photos taken at an angle, shadows across the page and very small print all hurt accuracy.
Rendering at 300 dpi can't add detail that a small, low-resolution photo never had, so take the photo close and sharp instead of counting on the tool. Tesseract from version 4 on expects dark text on a light background, which matters if your screenshots were taken in dark mode.
Printed text works far better than handwriting. Our guide to OCR for handwritten notes explains what to expect, and turning scanned receipts into text covers the small print on till slips.
What OCR PDF cannot do
The tool reads English only. Letters from other alphabets come out wrong, and accented letters often do too; our guide on OCR for PDFs in more than one language looks at that problem.
It takes PDFs, not image files. Turn a photo into a PDF first with Image to PDF or, for several photos, JPG to PDF from our tools that convert to PDF. With TIFF scans, turn sideways pages upright with Rotate Right in TIFF to PDF before converting.
Pages that already have readable text are left alone, so their text isn't doubled. A garbled page is rebuilt from a picture instead, which replaces its old text. Keep your original file either way.
A PDF that needs a password to open has to be unlocked first, for example with Unlock PDF if you know the password. The OCR copy keeps the original page images, so it comes out only a few KB bigger than the scan.
Want the recognized text as a plain text file? Run the OCR copy through PDF to TXT from our PDF conversion tools.
Frequently Asked Questions about OCR PDF
What does OCR do to a PDF?
It reads the letters in the page images and adds them as real text. With our tool, that text is an invisible layer over each page image.
Which languages does OCR PDF recognize?
English only. Text in other languages gets read with the English model and will contain errors.
Can I run OCR on a JPG or PNG image?
Not directly. Convert the image to PDF first, then run OCR on the PDF.
Will the OCR copy look like my original?
Yes. The original pages stay as they were, with the recognized text laid over them as an invisible layer, and keep their size, images and links. A page whose text was garbled is the exception: it becomes a 300 dpi picture of itself with new text.
Is the recognized text always correct?
No. OCR can mix up look-alike characters such as O and 0, so check names, numbers and dates against the scan.
How long do you keep my files?
Your scan and the OCR copy get deleted automatically within two hours. You don't need an account to use the tool.