
PDF to JSON Converter: Page Text, Headings and Metadata
Convert PDF to JSON online for free: your browser pulls out the text of every page and saves it as JSON with page numbers, likely headings and, if you want, the document metadata. The PDF never gets uploaded. Copy the result or download a .json file.
// how it works
How to convert a PDF to JSON in five steps
Upload a PDF, pick a JSON schema and check the extracted structure in the preview before you download.
- 01Upload your PDF with 'Choose Files', or drag and drop it
- 02Pick the JSON schema you want
- 03Click 'Convert to JSON' to start
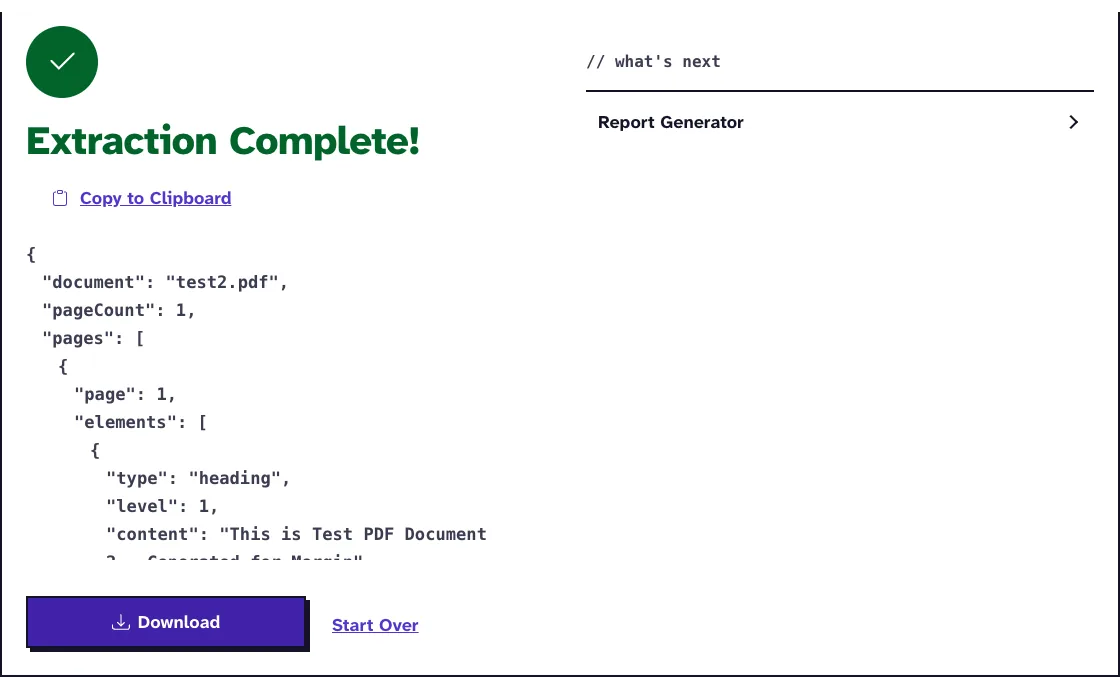
- 04Check the JSON preview on the results screen
- 05Copy it to the clipboard, or download the JSON file
PDF to JSON: schemas, heading detection and limits
A PDF looks the same on every device, but that fixed layout makes the text inside a pain to reuse in a script, a database or a search index. Converting PDF to JSON turns each page's text into data that programs can read.
Our free PDF to JSON converter extracts the readable text, marks likely headings, keeps page numbers and can add the document metadata. It all runs in your browser, so the PDF never gets uploaded.
Convert a PDF to JSON Online for FreeWhat is PDF to JSON conversion?
It reads the text and document properties of a PDF and writes them as JSON objects and arrays. JSON (RFC 8259) is a lightweight, text-based, language-independent data format, so almost every programming language, database and spreadsheet tool can load it.
In the PDF, a page is one visual surface. In the JSON, every page and every piece of text gets a fixed place in a data structure, with its page number attached.
How to convert PDF to JSON online
- Click “Choose Files” and pick one PDF (up to 25 MB), or drag it into the upload area.
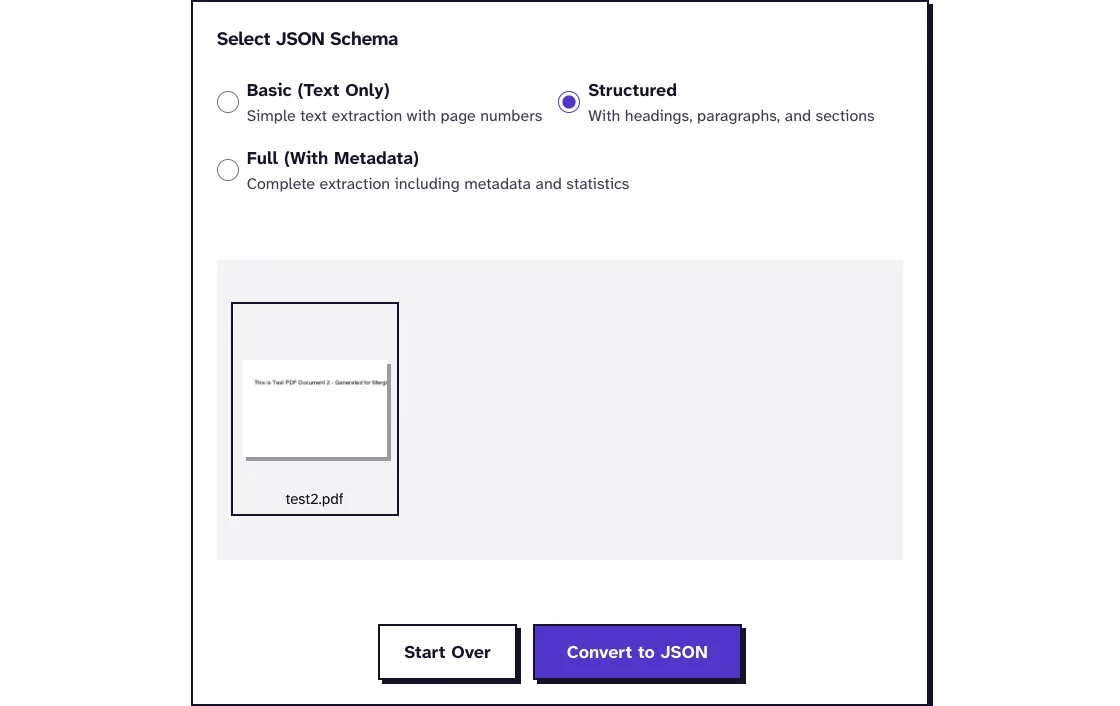
- Choose a schema: Basic, Structured or Full.
- Click Convert to JSON.
- Check the JSON preview on the results screen.
- Click Copy to Clipboard, or Download to save a .json file.
Choosing the right JSON schema
Basic: page text only
Each page gets its number and one text value. It's enough for a search index, a note-taking system or a quick script.
Structured: headings and paragraphs
Each page holds a list of elements, each marked as a heading or a paragraph, and headings also carry a level and a font size. Pick it for content migration, or for anything that has to tell a title from body text.
{
  "document": "report.pdf",
  "pageCount": 1,
  "pages": [
    {
      "page": 1,
      "elements": [
        { "type": "heading", "level": 1, "content": "Annual Report", "fontSize": 24 },
        { "type": "paragraph", "content": "Sales rose in every region..." }
      ]
    }
  ]
}
That's the shape of the Structured output (the values are made up).
Full: with metadata and statistics
Full adds the title, author, subject, keywords, creator, producer and the creation and modification dates when the PDF has them. It also adds a word count per page and totals for sections, headings and paragraphs.
Empty properties stay empty, because the converter won't guess missing values. If you want them filled in the PDF itself, use our Edit Metadata tool first.
How are headings and paragraphs detected?
The converter reads the pieces of text the PDF exposes with PDF.js, Mozilla's open-source library for parsing and rendering PDFs. A piece of text shorter than 100 characters counts as a heading when its text is 14 points tall or more, or when it contains only capital letters, digits, spaces and colons.
Headings of 20 points or more get level 1, 16 points or more level 2, and smaller ones level 3. Everything else between two headings gets joined into one paragraph, so check the result if a page uses lots of font sizes.
How accurate is the heading detection on a real document?
It finds the real headings reliably, but it also marks table figures and running headers as headings. In October 2026 we ran the converter's own extraction code, with PDF.js 5.4, on a three-page report with 3 titles at 20 points, 8 section headings at 16 points, a small table and an all-caps line at the top of each page.
All 11 real headings came out as headings, the titles at level 1 and the sections at level 2. Alongside them, the Structured JSON listed 9 false headings at level 3: the table's six cells QUARTER, VISITS, Q1, 1204, Q2 and 1356, and the running header NORTHWIND CLUB once per page.
Short cells made of capitals or digits match the capitals rule, so a page full of figures gives you a lot of false headings. Drop the level 3 headings in your script, or keep only level 1 and 2 if the outline is all you need.
What the converter cannot extract
Tables don't get rebuilt as rows and columns. Their cells come out as text in the order the PDF stores it, and cells of capitals or digits are marked as headings. For tables, use our PDF Table Extract tool, which writes rows and columns to a CSV file.
A scanned PDF holds pictures of text, so there's nothing to extract until the pages have been through OCR; our OCR PDF tool adds that text layer. Images, fonts and the visual layout aren't part of the JSON at all.
We can't read a PDF that needs a password to open, so take the password off first with one of our PDF security tools. If plain text is all you need, our PDF to TXT converter is simpler, and to pick dates, email addresses, phone numbers and amounts out of the text, use PDF Data Extraction.
Is the PDF uploaded?
No. The page reads the PDF in your browser and builds the JSON there, so the file never reaches PDF-File.com's server and there's nothing for us to delete. You don't need an account either.
What happened when we tested PDF to JSON
We converted our small test file test2.pdf (909 B, 1 page) with the Structured schema, the default. The download, test2_to_JSON.json, came to 293 B and was ready 0.2 seconds after we clicked.
Tested in October 2026.
Frequently Asked Questions about PDF to JSON
What is a PDF to JSON converter?
It's a tool that pulls out the text and document properties of a PDF and saves them as structured JSON objects and arrays.
Can I convert a scanned PDF to JSON?
Only after OCR. A scanned page is an image without a text layer, so run it through OCR PDF first.
Does the converter extract tables?
No. Table cells come out as ordinary text. Use PDF Table Extract to get rows and columns as CSV.
Which JSON schema should I choose?
Basic for page text only, Structured for headings and paragraphs, and Full when you also want metadata, word counts and totals.
Does the converter keep page numbers?
Yes. Every page in the JSON keeps its page number, so you can trace any text back to the PDF.
Is PDF to JSON free?
Yes. It's free, you don't need an account, and the PDF never leaves your browser.
Turn Your PDF Data into JSON