Extract Financial Data From PDF Statements: Text PDFs, Scans and Tables
How to get figures out of bank statements, invoices and reports into a spreadsheet, and how to check them once they're there.
To extract financial data from a PDF, first check whether the PDF has real text: if you can select the numbers, a table extractor such as our free Extract PDF Tables turns them into a CSV file in seconds. If the statement is a scan, run OCR on it first, then extract the table and check the figures against the original.
Whichever route you take, plan a check at the end. A single shifted column turns a debit into a balance, and nothing in the spreadsheet will tell you.
Is Your Financial PDF Text or a Scan?
Open the PDF and try to select a number with your mouse.
- The number highlights: the PDF holds text, usually because a bank or accounting system created it. Go straight to extracting the table.
- Only a box appears: it's a scan or a photo of the page. The figures are part of a picture, so you need OCR first.
Paper statements you scanned yourself are pictures.
Prepare the Files Before You Extract Anything
A few minutes here saves a lot of fixing later.
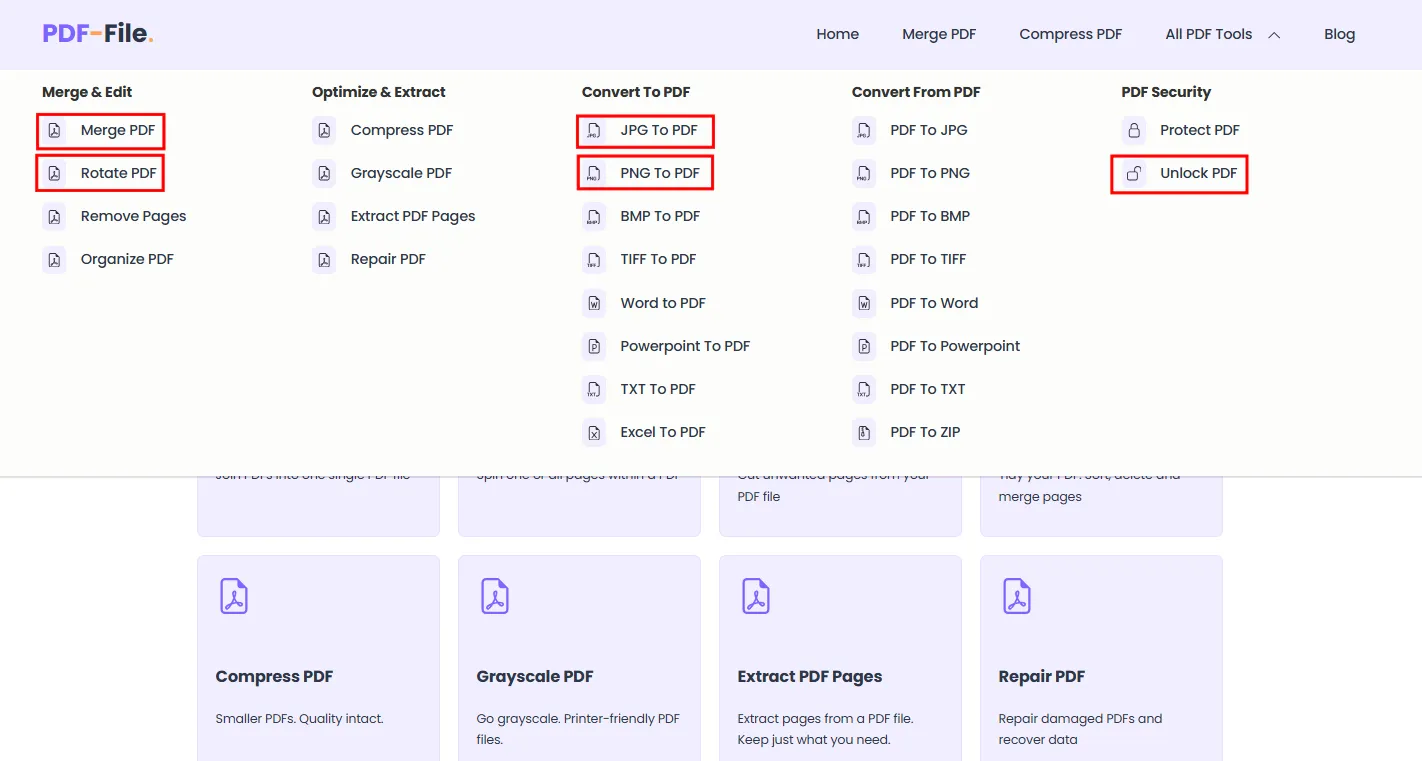
- Put the pages in one file. If the statement came as separate images, convert them with JPG to PDF and combine the files with Merge PDF.
- Turn sideways pages upright with Rotate PDF Pages. OCR reads crooked pages badly.
- Remove an open password. With the password, Unlock PDF gives you a copy the other tools can read.
How to Extract Financial Data From a Text PDF
For a statement or report with selectable text, a table extractor rebuilds the rows for you.
- Upload the PDF to Extract PDF Tables (up to 100 MB).
- Click Extract Table.
- Download the CSV and open it in Excel, Google Sheets or LibreOffice Calc.
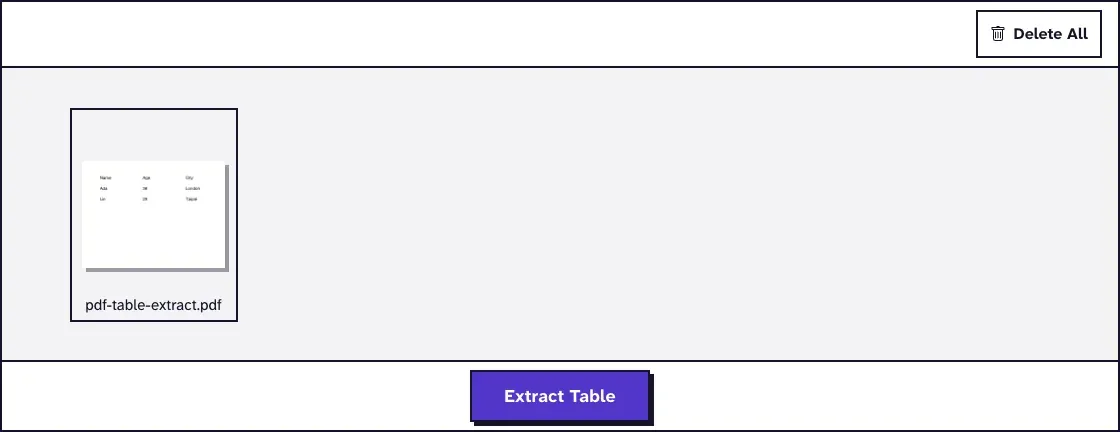
The tool puts text on the same line into one row and sorts it from left to right, and it writes the CSV so that amounts like "1,500.00" stay in one cell. In October 2026 we ran a two-page test statement with the columns Date, Description, Money in, Money out and Balance through it, one page of it rotated to landscape. We got the same five rows back for both pages, in a 459 B CSV.
One thing needed fixing by hand. The tool doesn't see column borders, so an empty cell leaves no gap: in rows with no Money in, the Money out amount moved one column to the left. Check those rows first.
If you'd rather have a workbook, PDF to Excel writes the text into an XLSX file, one row per line, with every cell as text. Our guide to converting a PDF to Excel for accounting covers turning those cells into real numbers and dates.
How to Extract Financial Data From a Scanned PDF
A scan needs optical character recognition before any table tool can read it. Our OCR PDF tool runs the open-source Tesseract engine on every page and adds the recognized text as an invisible layer over the scan. It reads English only.
Scan quality decides how good the numbers are. In our November 2026 test of OCR PDF, in Chrome on a Mac, one clean generated page at 300 or 200 dpi was read without a single wrong word, while the same page turned 3 degrees came back with 91 of 256 words right one way and 202 the other. So scan straight, at 200 to 300 dpi, before you blame the software.
After OCR, run the file through Extract PDF Tables and compare the totals with the scan.
Desktop OCR Software and Cloud Services
If you process statements every day, paid software can save time.
Adobe says Acrobat exports PDFs to Excel and runs text recognition on scanned text by itself. ABBYY FineReader PDF is sold on its OCR, and Tungsten Power PDF lists PDF to Excel for financial services. We didn't run any of them.
Which Cloud Services Return Tables
Amazon Textract, Azure Document Intelligence and Google Document AI all return tables to your own software. They all take your statements outside your network, so clear that first.
| Service | What its documentation says |
|---|---|
| Amazon Textract | Analyze Document with Tables |
| Azure Document Intelligence in Foundry Tools | Layout model for text and tables, and a bank statement model |
| Google Document AI | Form Parser and Layout Parser extract tables |
Prices as we read them in November 2026: Amazon Textract's tables cost $0.015 per page for the first million in US West (Oregon), and new customers get 100 pages a month free for three months. Azure lists a free tier of 500 pages a month.
Google Cloud Vision is the one to skip for this. Its PDF feature detects and transcribes text, and Google points to Document AI for structured parsing. Textract's plain Detect Document Text costs a tenth as much, $0.0015 a page, but that price isn't for tables.
Extracting Figures From Scanned PDFs With Python
If you can code, a short Python script gives you full control. Install the packages with pip install pytesseract pdf2image, then Tesseract from the Tesseract installation guide. Poppler comes from brew install poppler on a Mac and sudo apt-get install poppler-utils on Ubuntu; on Windows, pdf2image's install page has a download to unpack and add to your PATH.
For many statements in the same layout, our guide to what a PDF scraper is explains when a script like this is worth building.
The script turns each page into a 300 dpi image, reads it with Tesseract and pulls out amounts written like $1,250.00 with a regular expression:
1# Sample Python code for extracting text from scanned financial PDF
2import pytesseract
3from pdf2image import convert_from_path
4import re
5
6# Convert PDF to images
7pages = convert_from_path('financial_statement.pdf', 300)
8
9# Extract text using OCR
10text = ""
11for page in pages:
12    text += pytesseract.image_to_string(page)
13
14# Process financial data: Extract dollar amounts
15dollar_amounts = re.findall(r'\$\d+(?:,\d+)*(?:\.\d+)?', text)
16print(dollar_amounts)
A regular expression finds amounts, not their meaning, so pair each one with its date and description before you rely on it. It drops a minus sign and skips "$ 20.00" with a space, so check those on your statements.
How to Check the Extracted Figures
Extraction mistakes are quiet, so make checking part of the job.
- Totals: add up each column and compare it with the totals printed on the statement.
- Running balance: recalculate the balance row by row. A wrong digit or a shifted cell shows up at once.
- Formats: look for amounts stored as text, minus signs that became dashes, and dates read as month-day instead of day-month.
For bank statements headed into accounting software, our guides on bank statement PDF to CSV for QuickBooks and automating invoice extraction walk through the import step.
Frequently Asked Questions about Extracting Financial Data From PDFs
How do I extract a table from a bank statement PDF?
If the statement has selectable text, upload it to Extract PDF Tables and download the CSV. If it's a scan, run OCR PDF first, then extract the table and check the totals.
Can OCR read financial figures correctly?
From one clean, straight generated page at 200 to 300 dpi, our OCR test read every word. The same page tilted did much worse, so always compare totals with the original.
Is it safe to upload financial statements to an online tool?
Our tools process the file on our server and delete it within two hours, with no account needed. For documents your employer forbids uploading, use desktop software or the Python script on your own computer.
Why did my amounts end up in the wrong columns?
The extractor sorts text left to right and doesn't see column borders. When a cell is empty, the values after it move one column to the left, so fix those rows by hand.